The Skill Contract
· Hui Huang
The first time an AI agent handles a hard task, it feels like a breakthrough. The second time, you just want it to do the same thing again. That’s often where it falls apart. The prompt that produced a sharp report on Monday returns a different structure on Friday. The agent that summarized your inbox last week decides this week to draft replies. The model can do both. Being capable isn’t the same as running reliably.
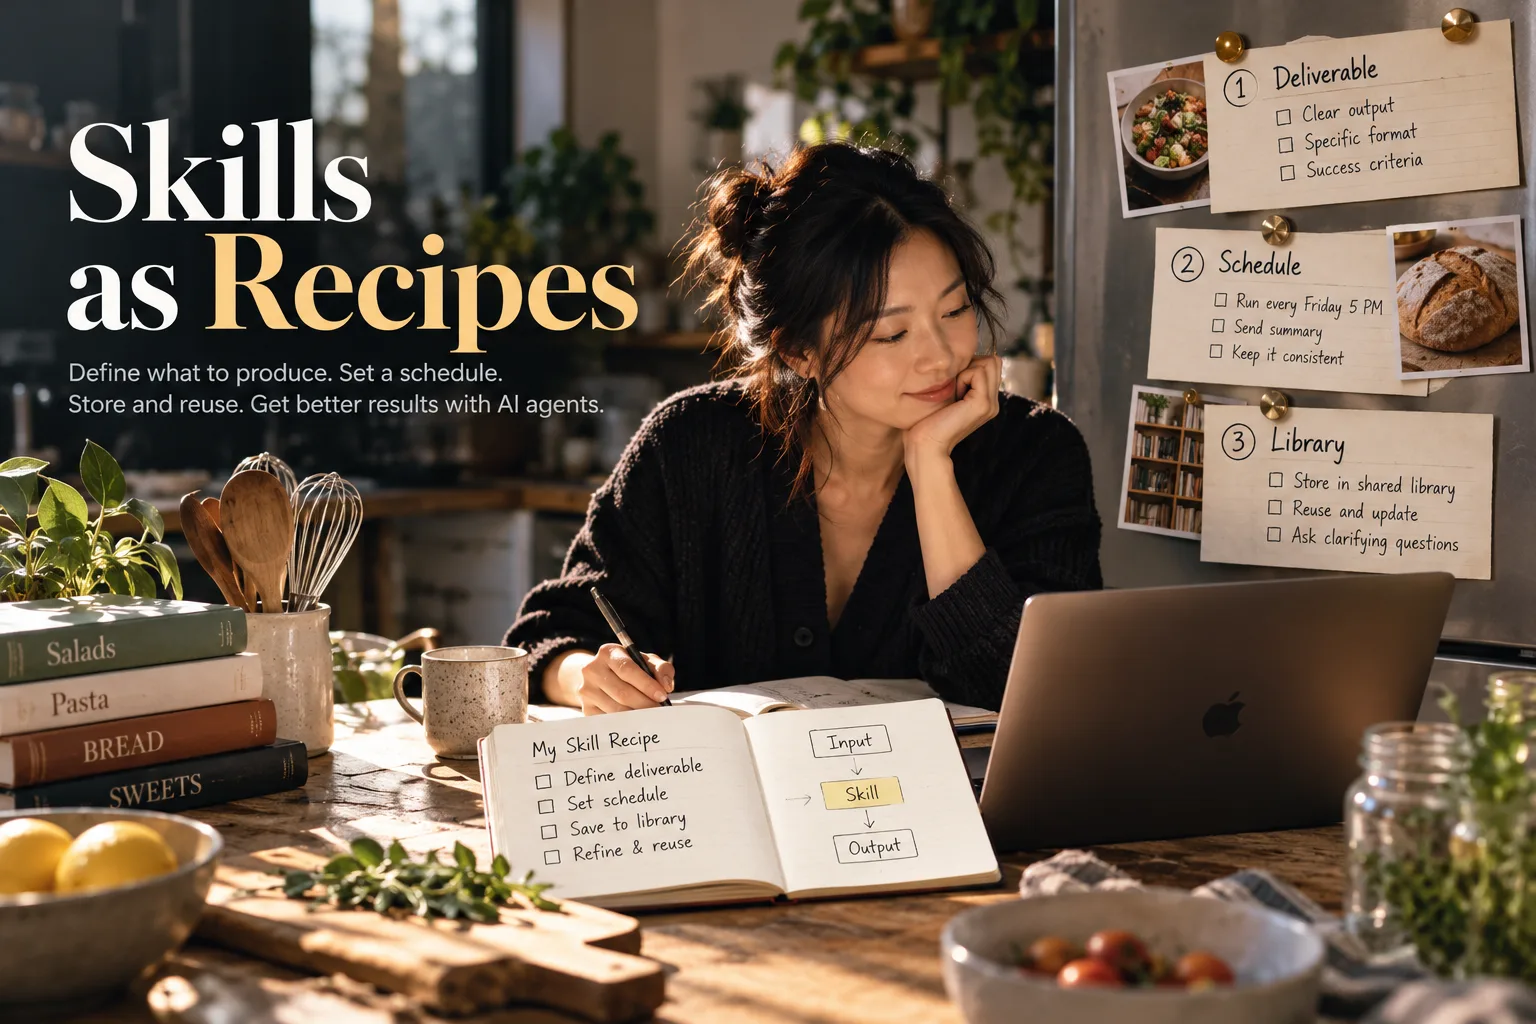
A useful way to think about an AI skill is as a recipe. A good recipe lists the ingredients, the method, and the result. You can reuse it, tweak it, and hand it to someone else. That beats asking an AI to “take care of email” and hoping. But for an agent with access to business systems, the recipe idea has a limit. A recipe tells you how to proceed. An operating contract also says when you’re allowed to proceed, what counts as success, and what to do when the evidence falls short.
An AI skill should be a reusable contract for producing an outcome, not just a saved prompt for performing steps.
Start with the deliverable
Say a business owner asks an agent to “analyze our customer emails every week.” A model can read that a dozen reasonable ways. It might summarize themes, rank customers by urgency, calculate response times, spot sales opportunities, or write an executive memo. A polished answer to the wrong question is still the wrong deliverable.
A stronger skill starts with the artifact: a spreadsheet with weekly inbound request counts, response-time spread, unresolved threads, and a separate list of conversations that need a human. Then pin down the window and the rules. What counts as a customer request? Is response time measured to the first human reply or the first auto-acknowledgement? Are internal messages excluded? Must every number trace back to a specific message?
This isn’t paperwork. It makes the task testable. A clear output format gives the agent a target, definitions keep the numbers meaningful, and links to the source messages let a person audit the result. If two people disagree on what counts as a response, no prompt can fix the metric. Someone has to decide before the first run.
Instructions aren’t permission
A saved skill might say: “Read the inbox, classify requests, calculate weekly metrics, and notify the team.” Each verb hides a different permission. Reading customer messages is one. Updating a spreadsheet is another. Emailing a distribution list has consequences outside the team. Sitting in the same workflow doesn’t make them equivalent.
This is where a skill becomes more than a recipe. It should declare which tools it can use, what data it can read, what it’s allowed to change, and when it must ask for approval. A reporting agent might be allowed to read one mailbox and update a draft report, but never share customer-level details outside the team. It should also pause when access expires, source data is incomplete, or it isn’t sure how to classify a customer.
So don’t only ask “Can this agent do this step?” Ask “Under what conditions should it?” A good agent sometimes decides not to act. That restraint is part of reliability, not a lack of intelligence.
A schedule repeats whatever you give it
A schedule turns AI from on-demand chat into a recurring service. A report that lands every Friday becomes part of a manager’s routine. But put a vague instruction on a schedule and you just get the vagueness every week, automatically.
A production skill needs clear run boundaries. If the window closes Friday at 5 p.m., in which time zone? What if a run misses its slot? Does the next one reprocess old messages or only new ones? What stops duplicate rows after a retry? How does a failed run get flagged before someone trusts an incomplete report?
These questions matter more when an unpredictable model sits inside an otherwise predictable process. Let ordinary software own timing, IDs, totals, and duplicate checks. Use the model where judgment is truly needed, like telling a new service request from an ongoing thread. Don’t ask a language model to improvise arithmetic or guess whether a job already ran when a database can answer exactly.
A shared library needs versions
Keeping skills in a shared library is a good instinct. You stop copying the same instructions into every agent, and you improve the work once for everyone. But a folder of prompt files isn’t automatically something the company can rely on.
Say someone changes what “unresolved” means. Old reports used one definition, new ones use another. Without versions, the team compares numbers that don’t match as if they did. Worse, an updated skill might quietly gain a new tool or start publishing results it used to only draft.
A reliable library makes its contracts easy to find and its changes deliberate. Each skill needs an owner, a version, a stated scope, and examples of good and bad results. Changes to output format or permissions deserve more review than wording tweaks. Before you roll out a new version, run it against a few known cases, including ambiguous emails and missing data. You can’t stop the model from ever varying. You can know whether the variation matters.
Test the boring cases
The best test of a skill isn’t one impressive demo. It’s whether a second agent, or the same one a month later, produces a result you can trust on an ordinary week.
For the weekly email report, I’d check four things:
- Completeness: did it include all the messages it should?
- Correctness: are the calculated numbers right?
- Traceability: can every exception be traced to its source?
- Escalation: does it refuse or ask for help when inputs fall short?
I’d also confirm the report reaches the right place exactly once. Together, that covers both judgment and operations.
Include cases where the right outcome isn’t a report. If the mailbox connection is broken, the agent should say so instead of inventing counts. If a classification rule is ambiguous, it should raise a short list of questions instead of quietly changing the definition. If publishing needs approval, a finished draft isn’t permission to send. Part of how a skill earns trust is by making its failures visible.
From prompt to practice
The order matters:
- Define the deliverable and how you’ll judge it.
- Specify the context, inputs, tools, and allowed side effects.
- Decide when the skill applies, when it must stop, and who resolves uncertainty.
- Only then add a schedule.
- Store and version it, test it on representative cases, and improve it from real failures.
Not every personal automation needs heavy process. Match the controls to the stakes. A skill that formats your private notes can stay light. One that contacts customers, changes financial records, or publishes company metrics needs firm boundaries. Reuse should save work without hiding who’s responsible.
A recipe’s lasting value isn’t that it replaces the cook. It makes a result teachable, repeatable, and improvable. AI skills can do the same for knowledge work, as long as we don’t mistake an instruction for a guarantee. A prompt describes what to try. A skill contract defines what must be true before you can trust the result.
Building skills your team can rely on? See how we approach Deployable AI.
Stay Updated
Get notified when we publish new insights on AI transformation